E-그래프로 Python 특수화하기
지금까지 우리는 수치 계산을 최적화하기 위한 점점 더 정교한 기법들을 살펴보았습니다. 기본적인 MLIR 개념에서 출발하여 메모리 관리와 선형대수를 거쳐 신경망 구현까지 다루었습니다. 각 계층은 계산을 표현하고 최적화하는 새로운 기능을 더해 주었습니다. 이제 Python 식을 위한 첫 번째 장난감 컴파일러를 만들 준비가 되었습니다.
이 절에서는 egglog 라이브러리를 사용하여 Python 식에 항 재작성과 최적화를 수행하고 이를 MLIR로 컴파일하는 방법을 살펴보겠습니다.
이 절의 전체 소스 코드는 GitHub에서 볼 수 있습니다.
동치 포화와 E-그래프
구현에 들어가기 전에 동치 포화와 e-그래프의 핵심 개념을 복습해 봅시다.
예를 들어 다음과 같은 재작성 규칙이 있다고 합시다.
x * 2→x << 1x*y/x→y
그리고 이를 (a * 2)/2 식에 적용하려고 하면 (a << 1)/2가 됩니다. 그러나 원래는 분자와 분모의 2를 약분하여 a를 얻었어야 하며, 그러면 더 간단한 식이 됩니다. 재작성 순서는 중요하며, 우리는 비용 함수에 따라 식을 어떤 형태로 줄여 주는 최적의 재작성 순서를 찾고자 합니다. 이를 단계 순서 문제(phase ordering problem)라고 합니다.
egg 라이브러리는 가능한 모든 재작성을 식에 빠짐없이 적용하는 접근 방식을 사용하며, e-그래프를 활용하여 단계 순서 문제를 효과적으로 해결합니다. 이 접근 방식을 사용하면 가능한 모든 재작성을 탐색한 뒤, 식의 가장 최적인 형태를 추출할 수 있습니다.
예를 들어 선형대수에서 전치나 곱셈 같은 NumPy 행렬 연산은 행렬의 모든 원소를 건드려야 하므로 비용이 꽤 큽니다. 하지만 연산 횟수를 줄이는 데 적용할 수 있는 항등식은 매우 다양합니다.
LLVM 같은 컴파일러는 물론 MLIR의 linalg 다이얼렉트조차도 이러한 항등식을 알지 못하므로, 재작성을 적용하여 비용이 큰 연산을 반드시 없앨 수 있는 것은 아닙니다. 그러나 상위 수준(우리의 Core 언어)에서는 e-그래프를 사용하여, MLIR로 로어링하기 전에 훨씬 더 효율적인 텐서 조작 연산을 만들어 낼 수 있습니다.
예를 들어 다음 항등식들은 선형대수에서 매우 흔히 쓰입니다.
Python으로는 다음과 같습니다.
np.transpose(A * B) = np.transpose(B) * np.transpose(A)
np.transpose(np.transpose(A)) == A
이러한 규칙을 적용하면 컴파일 시점에 NumPy 식을 최적화할 수 있으며, 이는 상당한 성능 향상으로 이어집니다. 예를 들어 우리 예제에서는 곱셈 하나와 전치 두 개로 이루어진 세 개의 루프를 곱셈 하나와 전치 하나로 이루어진 두 개의 루프로 줄이는 데 성공했습니다. 이 최적화는 계산을 단순화할 뿐만 아니라 효율도 높여 줍니다. NumPy를 사용하는 일반적인 코드에는 이러한 최적화 기회가 많으며, 이를 흔히 손쉽게 얻을 수 있는 성과(low-hanging fruit)라고 부릅니다. 이러한 최적화를 체계적으로 적용하면 필요한 연산 횟수를 줄여 수치 계산의 실행을 효율화할 수 있습니다. 이는 LLVM의 자동 벡터화가 작동하기도 전에 적용된다는 점에서 특히 유익한데, 식의 잠재력을 최대한 활용하여 더 빠른 실행 시간을 달성할 수 있기 때문입니다.
e-그래프(동치 그래프)는 서로 동치인 여러 표현식을 압축적으로 표현하는 자료 구조입니다. e-그래프는 표현식마다 하나의 정규형을 유지하는 대신, 동치인 표현식들의 클래스를 유지합니다. 이 접근 방식 덕분에 더 유연하고 효율적인 항 재작성이 가능합니다.
egglog 라이브러리로 기본적인 단순화를 수행하는 구체적인 예제를 살펴봅시다. 먼저 표현식 모델을 정의해야 합니다.
from __future__ import annotations
from egglog import *

class Num(Expr):
    def __init__(self, value: i64Like) -> None: ...

    @classmethod
    def var(cls, name: StringLike) -> Num: ...

    def __add__(self, other: Num) -> Num: ...

    def __mul__(self, other: Num) -> Num: ...

# Create an e-graph to store our expressions
egraph = EGraph()

# Define our expressions and give them names in the e-graph
expr1 = egraph.let("expr1", Num(2) * (Num.var("x") + Num(3)))  # 2 * (x + 3)
expr2 = egraph.let("expr2", Num(6) + Num(2) * Num.var("x"))    # 6 + 2x

# Define our rewrite rules using a decorated function
@egraph.register
def _num_rule(a: Num, b: Num, c: Num, i: i64, j: i64):
    yield rewrite(a + b).to(b + a)                    # Commutativity of addition
    yield rewrite(a * (b + c)).to((a * b) + (a * c))  # Distributive property
    yield rewrite(Num(i) + Num(j)).to(Num(i + j))     # Constant folding for addition
    yield rewrite(Num(i) * Num(j)).to(Num(i * j))     # Constant folding for multiplication

# Apply rules until no new equalities are found
egraph.saturate()

# Check if expr1 and expr2 are equivalent
egraph.check(eq(expr1).to(expr2))

# Extract the simplified form of expr1
egraph.extract(expr1)
egraph.display() 함수를 사용하면 e-그래프를 시각화할 수 있습니다.
동치 포화 이전의 입력 표현식은 다음과 같습니다.
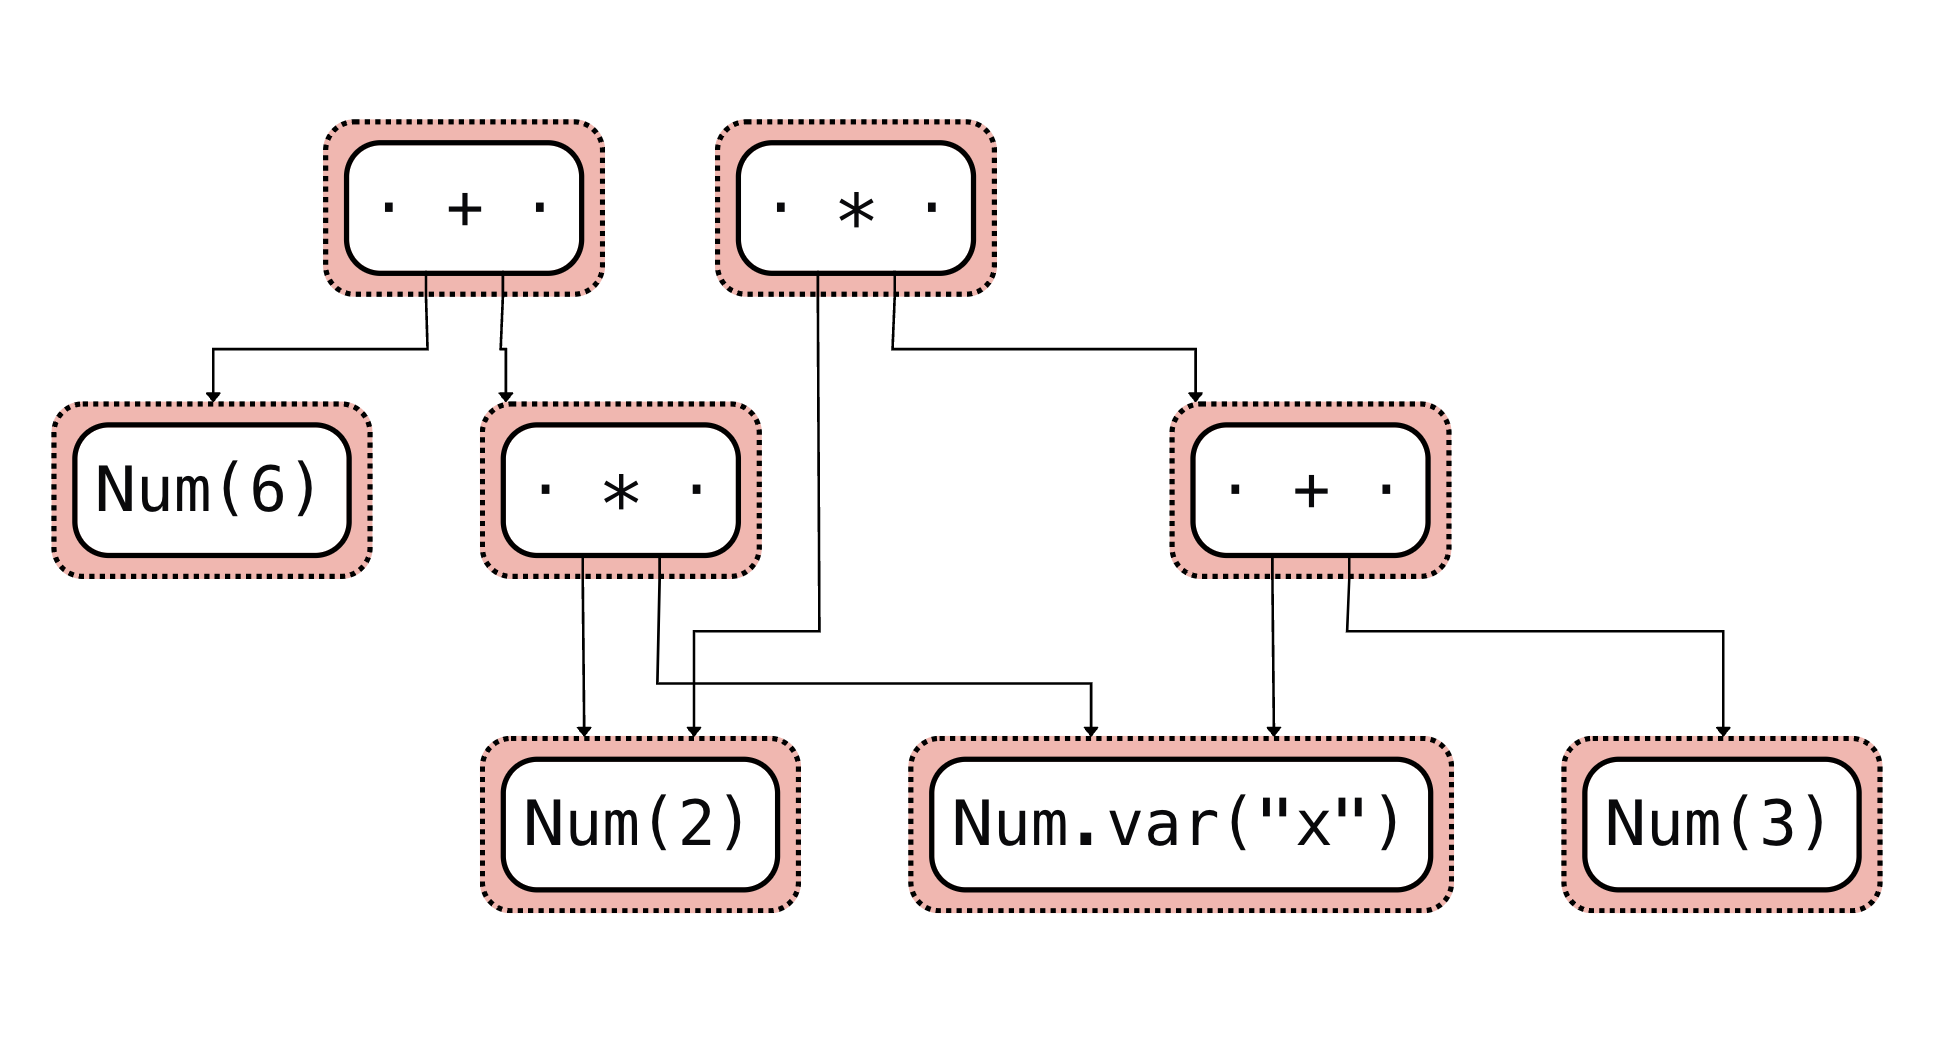 동치 포화 이전의 입력 표현식
그다음 모든 동치 클래스를 포함한 출력은 다음과 같이 표현식들의 네트워크가 됩니다.
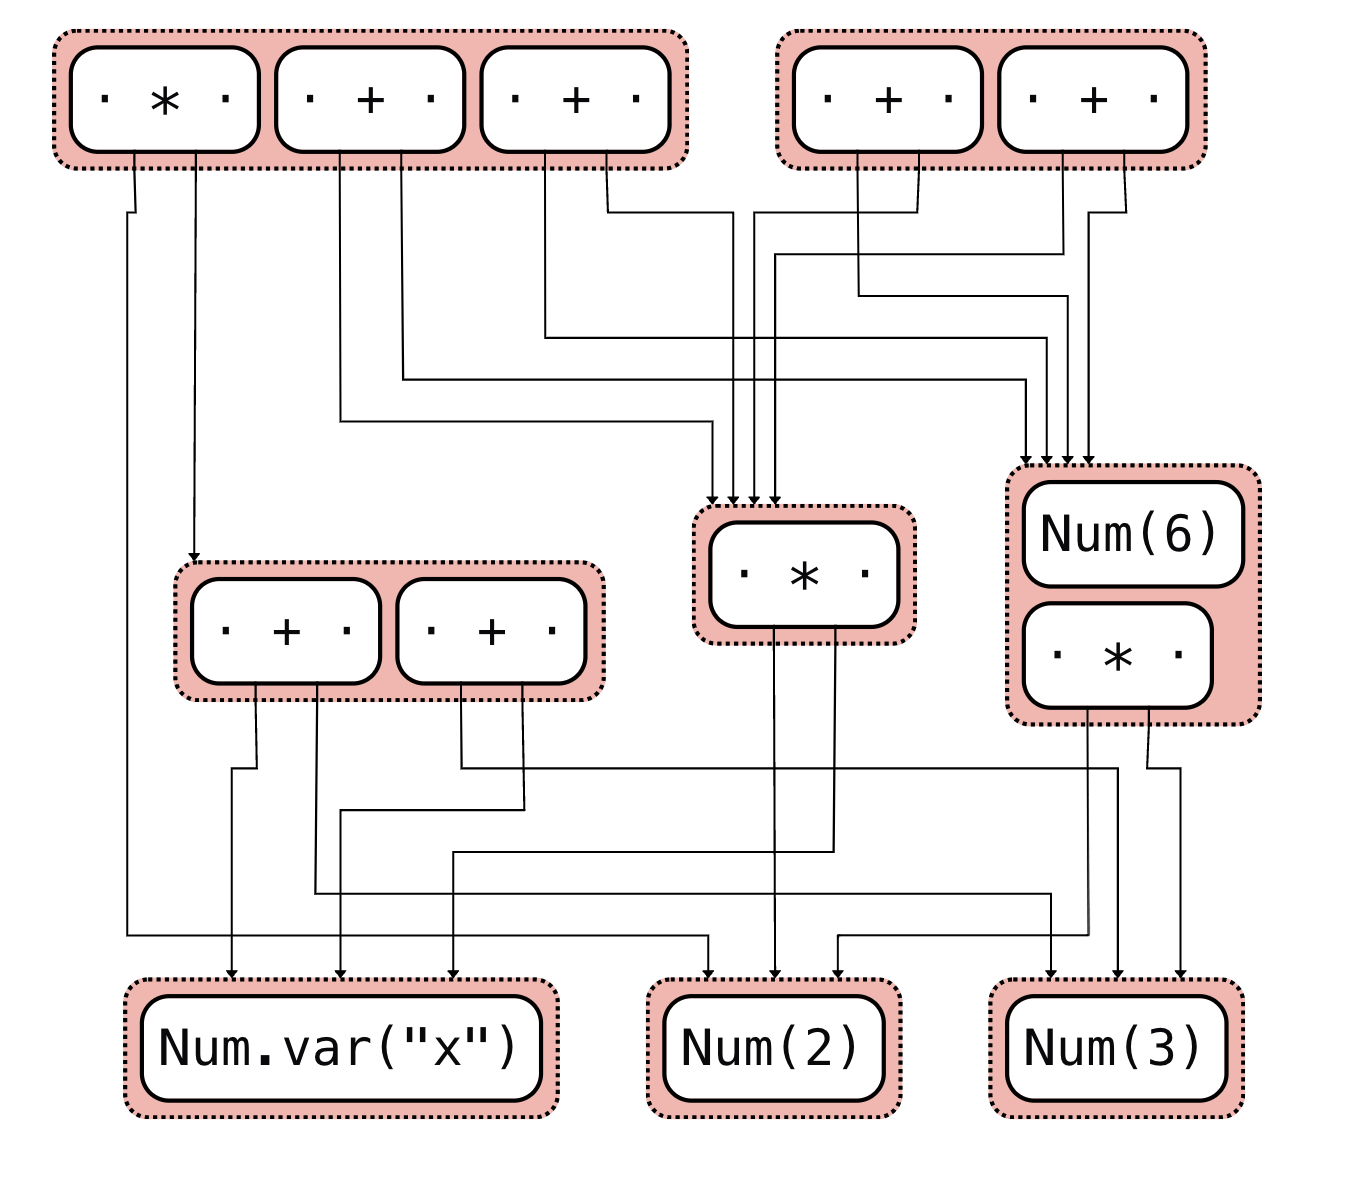 동치 포화 이후의 출력 표현식
여기에서 사용자 정의 비용 함수에 따라 원하는 표현식을 추출할 수 있습니다.
기반 계층
이제 이를 기본 표현식 컴파일러에 적용해 봅시다. 우리 컴파일러 파이프라인은 다음과 같은 몇 가지 핵심 단계로 이루어져 있습니다.
- Python 함수 데코레이션과 타입 어노테이션
- 표현식 트리 추출
- e-그래프를 이용한 항 재작성과 최적화
- MLIR 코드 생성
- LLVM 컴파일과 JIT 실행
우리 컴파일러의 기반 계층은 수학적 표현식을 표현하고 조작하기 위한 핵심(Core) 추상화를 제공합니다. 이 계층은 모든 상위 수준 최적화와 변환의 토대가 되므로 매우 중요합니다. 각 구성 요소를 자세히 살펴봅시다.
표현식 모델(expr_model.py)
우리 컴파일러의 중심에는 수학 표현식을 추상 구문 트리(AST)로 표현하는 표현식 모델이 있습니다. 이 모델은 깔끔하고 효율적인 표현을 위해 Python의 데이터클래스를 사용하여 구현되어 있습니다.
Core 표현식 타입
모든 표현식의 기본 클래스는 Expr 클래스이며, 이 클래스는 다음과 같은 기본 연산을 제공합니다.
@dataclass(frozen=True)
class Expr:
    def __add__(self, other: Expr) -> Expr:
        return Add(self, as_expr(other))

    def __mul__(self, other: Expr) -> Expr:
        return Mul(self, as_expr(other))
    # ... other operations
표현식 모델은 세 가지 기본 타입으로 구성됩니다.
-
리터럴: 표현식 안의 상수
@dataclass(frozen=True) class FloatLiteral(Expr): fval: float # Floating-point constant @dataclass(frozen=True) class IntLiteral(Expr): ival: float # Integer constant -
심볼: 변수와 함수 이름
@dataclass(frozen=True) class Symbol(Expr): name: str # Variable or function name -
연산: 단항 연산과 이항 연산 모두
@dataclass(frozen=True)
class UnaryOp(Expr):
    operand: Expr  # Single operand

@dataclass(frozen=True)
class BinaryOp(Expr):
    lhs: Expr  # Left-hand side
    rhs: Expr  # Right-hand side
@dataclass(frozen=True) class Add(BinaryOp): pass # Addition ... @dataclass(frozen=True) class Sin(UnaryOp): pass # Sine
내장 함수(builtin_functions.py)
내장 함수 모듈은 수학 연산을 위한 NumPy 스타일의 인터페이스를 제공합니다. 이를 통해 사용자는 익숙한 문법으로 식을 작성하면서도 저희 최적화 프레임워크를 그대로 활용할 수 있습니다. 이 모듈에는 자주 쓰이는 수학 상수와 절댓값 같은 연산을 위한 헬퍼 함수가 포함되어 있습니다.
# A mock NumPy namespace that we convert into our own expression model

import math
from mlir_egglog.expr_model import (
    sin,
    cos,
    tan,
    asin,
    acos,
    atan,
    tanh,
    sinh,
    cosh,
    sqrt,
    exp,
    log,
    log10,
    log2,
    float32,
    int64,
    maximum,
)  # noq

# Constants
e = math.e
pi = math.pi


# Define abs function
def abs(x):
    return maximum(x, -x)


def relu(x):
    return maximum(x, 0.0)


def sigmoid(x):
    return 1.0 / (1.0 + exp(-x))


__all__ = [
    "sin",
    "cos",
    "tan",
    "asin",
    "acos",
    "atan",
    "tanh",
    "sinh",
    "cosh",
    "sqrt",
    "exp",
    "log",
    "log10",
    "log2",
    "float32",
    "int64",
    "e",
    "pi",
    "maximum",
    "abs",
]
Term IR (term_ir.py)
Term IR 계층은 항 재작성과 동치 포화에 최적화된 중간 표현을 제공합니다. Term IR의 핵심 기능은 여러 연산에 대한 비용 모델입니다.
COST_BASIC_ARITH = 1   # Basic arithmetic (single CPU instruction)
COST_CAST = 2          # Type conversion operations
COST_DIV = 5           # Division
COST_POW_INTEGER = 10  # Integer power
COST_SQRT = 20         # Square root
COST_LOG = 30          # Logarithm
COST_EXP = 40          # Exponential
COST_POW = 50          # General power operation
COST_TRIG_BASIC = 75   # Basic trigonometric functions
COST_HYPERBOLIC = 180  # Hyperbolic functions
e-그래프 최적화 엔진은 이 비용을 바탕으로 어떤 변환을 적용할지 결정합니다. 이 비용은 대략 현대 하드웨어에서 각 연산이 갖는 계산 복잡도에 대응합니다.
from __future__ import annotations

import egglog
from egglog import StringLike, i64, f64, i64Like, f64Like  # noqa: F401
from egglog import RewriteOrRule, rewrite
from typing import Generator
from mlir_egglog.expr_model import Expr, FloatLiteral, Symbol, IntLiteral
from abc import abstractmethod

def as_egraph(expr: Expr) -> Term:
    """
    Convert a syntax tree expression to an egraph term.
    """
    from mlir_egglog import expr_model

    match expr:
        # Literals and Symbols
        case FloatLiteral(fval=val):
            return Term.lit_f32(val)
        case IntLiteral(ival=val):
            return Term.lit_i64(int(val))
        case Symbol(name=name):
            return Term.var(name)

        # Binary Operations
        case expr_model.Add(lhs=lhs, rhs=rhs):

        # Rest of the operations
        ...
비용 모델은 e-그래프 최적화 엔진이 이 비용 모델 기준으로 가장 비용 효율적인 구현을 찾도록 이끄는 데 사용됩니다. 예를 들면 다음과 같습니다.
좌변(LHS)에는 곱셈이 3번 있고 우변(RHS)에는 곱셈이 1번 있습니다. 따라서 추출 과정에 적용되는 비용에 따라 우변이 선택됩니다.
변환 계층
저희 컴파일러의 가장 강력한 기능 가운데 하나는 Python 함수를 기호적으로 해석하는 능력입니다. 이 과정은 일반 Python 함수를 저희 IR 표현으로 변환하며, 그 결과로 나온 식 트리에 최적화를 적용할 수 있게 해 줍니다.
해석 과정은 interpret 함수가 담당합니다.
import types
import inspect

from mlir_egglog import expr_model as ir


def interpret(fn: types.FunctionType, globals: dict[str, object]):
    """
    Symbolically interpret a python function.
    """
    # Get the function's signature
    sig = inspect.signature(fn)

    # Create symbolic parameters for each of the function's arguments
    params = [n for n in sig.parameters]
    symbolic_params = [ir.Symbol(name=n) for n in params]

    # Bind the symbolic parameters to the function's arguments
    ba = sig.bind(*symbolic_params)

    # Inject our globals (i.e. np) into the function's globals
    custom_globals = fn.__globals__.copy()
    custom_globals.update(globals)

    # Create a temporary function with our custom globals
    tfn = types.FunctionType(
        fn.__code__,
        custom_globals,
        fn.__name__,
        fn.__defaults__,
        fn.__closure__,
    )
    return tfn(*ba.args, **ba.kwargs)
이 함수는 먼저 매개변수 분석으로 시작하며, 입력 함수의 시그니처를 분석하여 매개변수를 파악합니다. 각 매개변수에 대해 저희 Symbol 클래스를 사용하여 기호 표현을 만듭니다. 이 기호들은 식 트리 전반에서 변수를 추적하는 데 사용됩니다.
다음으로 기호 매개변수를 함수의 인자 슬롯에 바인딩하여 매개변수 이름과 그 기호 표현 사이의 매핑을 만듭니다. 그런 다음 이 함수는 NumPy 함수와 같은 수학 연산에 대한 저희의 자체 구현을 해당 함수의 전역 네임스페이스에 주입합니다. 이를 통해 이러한 함수 호출을 가로채 저희의 기호 연산으로 대체할 수 있습니다.
원래 함수와 동일한 코드, 이름, 클로저를 유지하면서 수정된 전역 변수를 사용하는 임시 함수를 만듭니다. 마지막으로 기호 매개변수를 넣어 함수를 실행하면, 그 계산을 나타내는 식 트리가 만들어집니다.
예를 들어 다음과 같은 Python 함수가 있다고 합시다.
def f(x, y):
    return np.sin(x) + np.cos(y)
해석 과정은 다음을 수행합니다.
x와y에 대한 기호를 만듭니다np.sin과np.cos를 저희의 기호 버전으로 대체합니다- 기호 입력으로 함수를 실행합니다
Sin(Symbol("x")) + Cos(Symbol("y"))를 나타내는 식 트리를 반환합니다
바로 이 기호적 해석 덕분에 Python 계산을 저희 e-그래프 기법으로 최적화할 수 있는 형태로 포착할 수 있습니다.
IR 변환 (ir_to_mlir.py)
IR에서 MLIR로의 변환 계층은 우리의 고수준 표현식 표현과 MLIR의 저수준 다이얼렉트 사이를 잇는 중요한 다리 역할을 합니다. 이 변환 과정은 ir_to_mlir.py에 구현되어 있으며, AST 조작과 함께 Python의 동적 실행 기능을 활용하는 여러 단계로 이루어집니다.
변환 파이프라인은 IR 항을 내부 표현식 모델로 변환하는 convert_term_to_expr 함수에서 시작합니다. 이 함수는 Python의 내장 ast 모듈을 사용하여 항의 추상 구문 트리를 파싱하고 조작합니다. 이 과정이 특히 흥미로운 이유는 Python의 실행 환경을 변환 과정의 일부로 사용하기 때문입니다.
항이 변환을 위해 들어오면 먼저 AST 파싱을 거칩니다. 이 함수는 항의 문자열 표현으로부터 Python AST를 생성하며, 이를 통해 실행 전에 코드 구조를 조작할 수 있습니다. 이 과정의 핵심은 mangle_assignment 함수로, 표현식의 결과가 _out이라는 이름의 변수에 제대로 담기도록 보장합니다. 이 맹글링 단계는 실행 환경에서 최종 결과를 꺼내는 방법을 제공하므로 매우 중요합니다.
실행 환경은 연산 이름을 해당 구현에 매핑하는 function_map 딕셔너리를 사용하여 신중하게 구성됩니다. 이 맵에는 기본 산술 연산(Add, Sub, Mul, Div), 수학 함수(Sin, Cos, Exp, Log), 타입 변환 연산(CastF32, CastI64)이 포함됩니다. 이 연산들은 각각 표현식 모델의 메서드나 내장 함수 모듈의 함수 중 하나에 매핑됩니다.
두 번째 주요 구성 요소는 convert_term_to_mlir 함수로, 변환된 표현식을 받아 MLIR 코드를 생성합니다. 이 함수는 MLIR의 텍스트 형식으로의 최종 변환을 담당합니다. 이 함수는 argspec 매개변수를 통해 함수 인수를 처리하며, 인수 이름과 그에 대응하는 MLIR 표현 사이의 매핑을 만듭니다(예: x를 %arg_x로 변환). 실제 MLIR 생성은 MLIRGen 클래스에 위임되며, 이 클래스는 표현식 트리를 순회하면서 대응하는 MLIR 연산을 생성합니다.
예를 들어 a + b * c 같은 간단한 산술 표현식을 변환할 때 파이프라인은 다음과 같이 동작합니다.
- 표현식을 AST로 파싱합니다
- 함수 맵을 사용하여 내부 표현식 모델로 변환합니다
- 적절한 메모리 참조와 연산을 갖춘 MLIR 코드를 생성합니다
- 적절한 타입 주석과 함께 연산들을 올바른 MLIR 함수 구조로 감쌉니다
def convert_term_to_expr(tree: IRTerm) -> ir.Expr:
    """
    Convert a term to an expression.
    """

    # Parse the term into an AST
    astree = ast.parse(str(tree))

    # Mangle the assignment
    astree.body[-1] = ast.fix_missing_locations(mangle_assignment(astree.body[-1]))  # type: ignore

    # Execute the AST
    globals: dict[str, Any] = {}
    exec(compile(astree, "<string>", "exec"), function_map, globals)

    # Get the result
    result = globals["_out"]
    return result


def convert_term_to_mlir(tree: IRTerm, argspec: str) -> str:
    """
    Convert a term to MLIR.
    """

    expr = convert_term_to_expr(tree)
    argnames = map(lambda x: x.strip(), argspec.split(","))
    argmap = {k: f"%arg_{k}" for k in argnames}
    source = MLIRGen(expr, argmap).generate()
    return source
최적화 계층
이제 표현식 트리에 적용할 재작성 규칙을 직접 작성해 봅시다.
birewrite_subsume 헬퍼 함수는 e-그래프용 재작성 규칙을 내놓는 생성기입니다. 이 함수는 두 항을 받아 첫 번째 항을 두 번째 항으로 변환하는 재작성 규칙을 생성하며, 이때 첫 번째 항은 더 이상 매칭되거나 추출될 수 없게 됩니다. 우리는 이를 사용하여 일반 Term을 특수화된 이항 및 단항 연산으로 단방향 변환합니다.
def birewrite_subsume(a: Term, b: Term) -> Generator[RewriteOrRule, None, None]:
    yield rewrite(a, subsume=True).to(b)
    yield rewrite(b).to(a)
기본 단순화 모듈은 항 재작성 시스템의 토대가 되는 기본적인 수학적 재작성을 구현합니다. 이 규칙들은 basic_math 규칙 집합으로 구성되어 있으며, 다음과 같은 몇 가지 주요 변환 범주를 포함합니다.
- 항 변환 규칙: 일반 Term과 그 특수화된 형태(Add, Mul, Div, Pow) 사이의 변환을 가능하게 하는 규칙입니다
- 항등 규칙: , 같은 수학적 항등식을 처리하는 규칙입니다
- 결합 법칙 규칙: 같은 연산의 결합 법칙을 처리하는 규칙입니다
- 거듭제곱 규칙: , 같은 경우를 포함하여 거듭제곱을 특별히 처리하는 규칙입니다
- 산술 단순화: 와 같은 일반적인 산술 패턴을 단순화하는 규칙입니다
각 규칙은 egglog의 재작성 시스템을 사용하여 구현됩니다.
from mlir_egglog.term_ir import Term, Add, Mul, Div, Pow, PowConst, birewrite_subsume
from egglog import RewriteOrRule, ruleset, rewrite, i64, f64
from typing import Generator


@ruleset
def basic_math(
    x: Term, y: Term, z: Term, i: i64, f: f64
) -> Generator[RewriteOrRule, None, None]:
    # Allow us to translate Term into their specializations
    yield from birewrite_subsume(x + y, Add(x, y))
    yield from birewrite_subsume(x * y, Mul(x, y))
    yield from birewrite_subsume(x / y, Div(x, y))
    yield from birewrite_subsume(x**y, Pow(x, y))

    # x + 0 = x (integer case)
    yield rewrite(Add(x, Term.lit_i64(0))).to(x)
    # x + 0.0 = x (float case)
    yield rewrite(Add(x, Term.lit_f32(0.0))).to(x)
    # 0.0 + x = x (float case)
    yield rewrite(Add(Term.lit_f32(0.0), x)).to(x)

    # x * 1 = x
    yield rewrite(Mul(x, Term.lit_i64(1))).to(x)

    # x * 0 = 0
    yield rewrite(Mul(x, Term.lit_i64(0))).to(Term.lit_i64(0))

    # (x + y) + z = x + (y + z)
    yield rewrite(Add(x, Add(y, z))).to(Add(Add(x, y), z))

    # (x * y) * z = x * (y * z)
    yield rewrite(Mul(x, Mul(y, z))).to(Mul(Mul(x, y), z))

    # x + x = 2 * x
    yield rewrite(Add(x, x)).to(Mul(Term.lit_i64(2), x))

    # x * x = x^2
    yield rewrite(Mul(x, x)).to(Pow(x, Term.lit_i64(2)))

    # (x^y) * (x^z) = x^(y + z)
    yield rewrite(Pow(x, y) * Pow(x, z)).to(Pow(x, Add(y, z)))

    # x^i = x * x^(i - 1)
    yield rewrite(Pow(x, Term.lit_i64(i))).to(PowConst(x, i))

    # x^0 = 1
    yield rewrite(PowConst(x, 0)).to(Term.lit_f32(1.0))

    # x^1 = x
    yield rewrite(PowConst(x, 1)).to(x)

    # x^i = x * x^(i - 1)
    yield rewrite(PowConst(x, i)).to(Mul(x, PowConst(x, i - 1)), i > 1)
기본 단순화 모듈과 마찬가지로, 삼각함수 단순화 모듈은 삼각함수와 쌍곡선 함수가 포함된 식을 단순화하기 위한 포괄적인 규칙 집합을 제공합니다. trig_simplify 규칙 집합은 몇 가지 중요한 범주의 변환을 구현합니다.
- 기본 항등식: $ \sin^2(x) + \cos^2(x) = 1 $와 같은 Core 삼각함수 항등식입니다
- 배각 공식: $ \sin(x + y) $ 및 $ \cos(x + y) $와 같은 식을 단순화하는 규칙입니다
- 쌍곡선 항등식: $ \sinh $, $ \cosh $, $ \tanh $에 대한 항등식을 포함하여 쌍곡선 함수에 대한 유사한 규칙입니다
이러한 규칙은 과학 계산과 머신러닝 응용에서 흔히 쓰이는 삼각함수가 포함된 수치 계산을 최적화하는 데 특히 중요합니다. 이 모듈은 Term IR에 정의된 비용 모델을 사용해 결정을 내리면서, 식 단순화와 계산 효율성 사이의 트레이드오프를 신중하게 조율합니다.
from mlir_egglog.term_ir import Sin, Cos, Sinh, Cosh, Tanh, Term, Pow, Add
from egglog import ruleset, i64, f64
from egglog import rewrite


@ruleset
def trig_simplify(x: Term, y: Term, z: Term, i: i64, fval: f64):
    # Fundamental trig identities
    # sin²(x) + cos²(x) = 1
    two = Term.lit_i64(2)
    yield rewrite(Add(Pow(Sin(x), two), Pow(Cos(x), two))).to(Term.lit_f32(1.0))

    # Double angle formulas
    yield rewrite(Sin(x + y)).to(Sin(x) * Cos(y) + Cos(x) * Sin(y))
    yield rewrite(Sin(x - y)).to(Sin(x) * Cos(y) - Cos(x) * Sin(y))
    yield rewrite(Cos(x + y)).to(Cos(x) * Cos(y) - Sin(x) * Sin(y))
    yield rewrite(Cos(x - y)).to(Cos(x) * Cos(y) + Sin(x) * Sin(y))

    # Hyperbolic identities
    yield rewrite(Sinh(x) * Cosh(y) + Cosh(y) * Sinh(x)).to(Sinh(x + y))
    yield rewrite(Cosh(x) * Cosh(y) + Sinh(x) * Sinh(y)).to(Cosh(x + y))
    yield rewrite((Tanh(x) + Tanh(y)) / (Term.lit_i64(1) + Tanh(x) * Tanh(y))).to(
        Tanh(x + y)
    )
Egglog 최적화기(egglog_optimizer.py)
최적화 엔진은 모든 재작성 규칙을 하나로 묶고, Python 함수에 최적화를 적용하기 위한 주요 인터페이스를 제공합니다. 이 엔진은 몇 가지 핵심 구성 요소로 이루어져 있습니다.
- 규칙 합성: 여러 규칙 집합을 순차적으로 또는 병렬로 결합하는 기능입니다
- 식 추출: Python AST와 항 표현 사이를 변환하는 로직입니다
- 최적화 파이프라인: 고정점에 도달할 때까지 규칙을 적용하는 체계적인 방식입니다
- MLIR 생성: 최적화된 식을 MLIR 코드로 변환하는 최종 단계입니다
최적화기는 e-그래프 자료 구조를 사용하여 동등한 식을 효율적으로 탐색하고, 비용 모델에 따라 가장 비용 효율적인 구현을 찾습니다.
import inspect
from types import FunctionType

from egglog import EGraph, RewriteOrRule, Ruleset
from egglog.egraph import UnstableCombinedRuleset

from mlir_egglog.term_ir import Term, as_egraph
from mlir_egglog.python_to_ir import interpret
from mlir_egglog import builtin_functions as ns
from mlir_egglog.expr_model import Expr
from mlir_egglog.ir_to_mlir import convert_term_to_mlir

# Rewrite rules
from mlir_egglog.basic_simplify import basic_math
from mlir_egglog.trig_simplify import trig_simplify

OPTS: tuple[Ruleset | RewriteOrRule, ...] = (basic_math, trig_simplify)


def extract(ast: Expr, rules: tuple[RewriteOrRule | Ruleset, ...], debug=False) -> Term:
    root = as_egraph(ast)

    egraph = EGraph()
    egraph.let("root", root)

    # The user can compose rules as (rule1 | rule2) to apply them in parallel
    # or (rule1, rule2) to apply them sequentially
    for opt in rules:
        if isinstance(opt, Ruleset):
            egraph.run(opt.saturate())
        elif isinstance(opt, UnstableCombinedRuleset):
            egraph.run(opt.saturate())
        else:
            # For individual rules, create a temporary ruleset
            temp_ruleset = Ruleset("temp")
            temp_ruleset.append(opt)
            egraph.run(temp_ruleset.saturate())

    extracted = egraph.extract(root)

    # if debug:
    #     egraph.display()

    return extracted


def compile(
    fn: FunctionType, rewrites: tuple[RewriteOrRule | Ruleset, ...] = OPTS, debug=True
) -> str:
    # Convert np functions accordinging to the namespace map
    exprtree = interpret(fn, {"np": ns})
    extracted = extract(exprtree, rewrites, debug)

    # Get the argument spec
    argspec = inspect.signature(fn)
    params = ",".join(map(str, argspec.parameters))

    return convert_term_to_mlir(extracted, params)
이 모듈들은 함께 작동하여 수학 식, 특히 삼각함수와 초월함수가 포함된 식을 최적화하는 강력한 시스템을 제공합니다. 이 시스템은 확장 가능하여 새로운 규칙을 쉽게 추가할 수 있으며, 그 위에 더 특화된 최적화를 구축하기 위한 견고한 기반을 제공합니다.
egglog 최적화기는 재작성 규칙을 합성하는 두 가지 방법, 즉 병렬 합성과 순차 합성을 지원합니다. 규칙을 | 연산자로 결합하면(병렬 합성), 규칙들은 e-그래프 포화 과정의 같은 반복 안에서 동시에 적용됩니다. 이를 통해 여러 변환을 동시에 탐색할 수 있습니다. 반면에 규칙을 튜플이나 시퀀스로 결합하면(순차 합성), 규칙들은 차례로 적용되며, 각 규칙 집합은 다음 규칙 집합으로 넘어가기 전에 포화 상태에 이를 때까지 실행됩니다. 이러한 순차적 방식은 특정 변환을 다른 변환이 완료된 후에만 시도해야 할 때 유용할 수 있습니다.
# Example 1: Parallel Composition
# Both rulesets are applied simultaneously in each iteration
parallel_rules = simplify_adds | simplify_muls
egraph = EGraph()
egraph.run(parallel_rules.saturate())

# Example 2: Sequential Composition
# simplify_adds runs to completion before simplify_muls starts
sequential_rules = (simplify_adds, simplify_muls)
egraph = EGraph()
for ruleset in sequential_rules:
    egraph.run(ruleset.saturate())
MLIR 생성(mlir_gen.py)
MLIR 코드 생성기는 최적화된 식 트리를 실행 가능한 MLIR 코드로 변환하는 역할을 맡습니다. 생성기는 N차원 배열을 효율적으로 처리할 수 있는 벡터화된 커널을 만들어 내기 위해 체계적인 방식을 따릅니다. 핵심 구성 요소와 설계 원칙을 살펴봅시다.
생성기는 다음 템플릿을 따르는 함수를 생성합니다.
func.func @kernel_worker(
    %arg0: memref<?xf32>,
    %arg1: memref<?xf32>
) {
    // Kernel body
}
생성된 커널은 입력 버퍼와 출력 버퍼라는 두 개의 memref 인자를 받아 affine 루프로 원소별 처리를 합니다. 이러한 설계 덕분에 임의 차원의 배열에 대해 효율적인 벡터화 연산을 수행할 수 있습니다.
func.func @kernel_worker(
    %arg0: memref<?xf32>,
    %arg1: memref<?xf32>
) attributes {llvm.emit_c_interface} {
    %c0 = arith.constant 0 : index

    // Get dimension of input array
    %dim = memref.dim %arg0, %c0 : memref<?xf32>

    // Process each element in a flattened manner
    affine.for %idx = %c0 to %dim {
        // Kernel body
    }
    return
}
식 변환
MLIRGen 클래스는 다중 패스 번역 전략을 구현합니다. 이 전략은 하위 표현식 확장에서 시작하며, 이 단계에서 생성기는 unfold 메서드를 사용해 표현식 트리를 펼쳐 하위 표현식의 완전한 집합을 만듭니다. 이 과정을 통해 공통 하위 표현식이 식별되고 재사용될 수 있습니다. 다음으로 생성기는 위상 정렬을 사용해 하위 표현식을 복잡도 순으로 정렬하는데, 문자열 길이를 복잡도의 대용 지표로 삼아 더 단순한 표현식이 그에 의존할 수 있는 더 복잡한 표현식보다 먼저 평가되도록 합니다. 마지막으로 코드 생성 파이프라인이 실행되며, 이 파이프라인은 먼저 memref에서 입력 변수를 로드하고, 하위 표현식에 대한 중간 계산을 생성한 뒤, 최종 결과를 출력 memref에 다시 저장합니다.
생성기는 중복 계산을 피하기 위해 영리한 캐싱 메커니즘을 사용합니다:
def walk(self, expr: ir.Expr):
    if expr in self.cache:
        return
    def lookup(e):
        return self.cache.get(e) or as_source(e, self.vars, lookup)
    self.cache[expr] = as_source(expr, self.vars, lookup)
이 캐싱 전략을 통해 각 하위 표현식은 정확히 한 번만 계산되고, 공통 하위 표현식은 MLIR의 SSA(Static Single Assignment) 형식을 통해 재사용되며, 생성된 코드는 최적의 효율을 유지합니다.
MLIR 다이얼렉트 사용
그다음 생성기는 표현식 트리를 순회하면서 고수준 표현식을 적절한 MLIR 다이얼렉트에 대응시킵니다:
- 산술 연산은
arith다이얼렉트를 사용합니다(예:arith.addf,arith.mulf) - 수학 함수는
math다이얼렉트를 사용합니다(예:math.sin,math.exp) - 메모리 연산은 배열 접근을 위해
memref다이얼렉트를 사용합니다 - 루프 구조는 최적화된 반복을 위해
affine다이얼렉트를 사용합니다
예를 들어 sin(x) + cos(y) 같은 Python 표현식은 다음과 같이 번역됩니다:
%sin = math.sin %arg_x : f32
%cos = math.cos %arg_y : f32
%result = arith.addf %sin, %cos : f32
생성기는 타입 변환을 자동으로 처리하며, 부동소수점 연산은 f32로 통일하고 정수 연산에는 상황에 맞게 i32 또는 i64를 사용합니다. 필요한 경우에는 정수를 부동소수점 값으로 변환하는 arith.sitofp와 같은 명시적 타입 캐스트가 생성됩니다. 이 타입 시스템은 MLIR의 엄격한 타입 요구 사항과의 호환성을 유지하면서 타입 안전성을 보장합니다.
from textwrap import indent
from typing import Callable
from mlir_egglog import expr_model as ir

KERNEL_NAME = "kernel_worker"

# Numpy vectorized kernel that supports N-dimensional arrays
kernel_prologue = f"""
func.func @{KERNEL_NAME}(
    %arg0: memref<?xf32>,
    %arg1: memref<?xf32>
) attributes  \{\{
    %c0 = arith.constant 0 : index

    // Get dimension of input array
    %dim = memref.dim %arg0, %c0 : memref<?xf32>

    // Process each element in a flattened manner
    affine.for %idx = %c0 to %dim \{\{
"""

kernel_epilogue = """
    }
    return
}
"""


class MLIRGen:
    """
    Generate textual MLIR from a symbolic expression.
    """

    root: ir.Expr
    cache: dict[ir.Expr, str]
    subexprs: dict[str, str]
    vars: list[str]  # local variables

    def __init__(self, root: ir.Expr, argmap: dict[str, str]):
        # Use the keys from argmap as the variable names
        self.root = root
        self.cache = {}
        self.vars = list(argmap.keys())
        self.subexprs = {}

    def generate(self):
        """
        Generate MLIR code for the root expression.
        """
        subexprs = list(self.unfold(self.root))
        subexprs.sort(key=lambda x: len(str(x)))

        buf = []
        # First load input arguments from memref
        for var in self.vars:
            buf.append(f"%arg_{var} = affine.load %arg0[%idx] : memref<?xf32>")

        for i, subex in enumerate(subexprs):
            # Skip if this is just a variable reference
            if isinstance(subex, ir.Symbol) and subex.name in self.vars:
                continue

            # Recurse and cache the subexpression
            self.walk(subex)
            orig = self.cache[subex]

            # Generate a unique name for the subexpression
            k = f"%v{i}"
            self.cache[subex] = k
            self.subexprs[k] = orig

            # Append the subexpression to the buffer
            buf.append(f"{k} = {orig}")

        self.walk(self.root)
        res = self.cache[self.root]

        # Handle the output
        buf.append(f"affine.store {res}, %arg1[%idx] : memref<?xf32>")

        # Format the kernel body
        kernel_body = indent("\n".join(buf), "    " * 2)
        return kernel_prologue + kernel_body + kernel_epilogue

    def unfold(self, expr: ir.Expr):
        """
        Unfold an expression into a set of subexpressions.
        """
        visited = set()
        all_subexprs = set()
        to_visit = [expr]
        while to_visit:
            current = to_visit.pop()
            all_subexprs.add(current)
            if current in visited:
                continue
            visited.add(current)
            to_visit.extend(get_children(current))

        return all_subexprs

    def walk(self, expr: ir.Expr):
        """
        Walk an expression recursively and generate MLIR code for subexpressions,
        caching the intermediate expressions in a lookup table.
        """
        if expr in self.cache:
            return

        def lookup(e):
            return self.cache.get(e) or as_source(e, self.vars, lookup)

        self.cache[expr] = as_source(expr, self.vars, lookup)


def get_children(expr: ir.Expr):
    """Get child expressions for an AST node."""
    match expr:
        case ir.BinaryOp():
            return {expr.lhs, expr.rhs}
        case ir.UnaryOp():
            return {expr.operand}
        case ir.FloatLiteral() | ir.IntLiteral() | ir.Symbol():
            return set()
        case _:
            raise NotImplementedError(f"Unsupported expression type: {type(expr)}")


def as_source(
    expr: ir.Expr, vars: list[str], lookup_fn: Callable[[ir.Expr], str]
) -> str:
    """
    Convert expressions to MLIR source code using arith and math dialects.
    """
    match expr:
        # Literals and Symbols
        case ir.FloatLiteral(fval=val):
            return f"arith.constant {val:e} : f32"
        case ir.IntLiteral(ival=val):
            return f"arith.constant {val} : i32"
        case ir.Symbol(name=name) if name in vars:
            return f"%arg_{name}"
        case ir.Symbol(name=name):
            return f"%{name}"

        # Binary Operations
        case ir.Add(lhs=lhs, rhs=rhs):
            return f"arith.addf {lookup_fn(lhs)}, {lookup_fn(rhs)} : f32"
        case ir.Mul(lhs=lhs, rhs=rhs):
            return f"arith.mulf {lookup_fn(lhs)}, {lookup_fn(rhs)} : f32"
        case ir.Div(lhs=lhs, rhs=rhs):
            return f"arith.divf {lookup_fn(lhs)}, {lookup_fn(rhs)} : f32"
        case ir.Maximum(lhs=lhs, rhs=rhs):
            return f"arith.maximumf {lookup_fn(lhs)}, {lookup_fn(rhs)} : f32"

        # Unary Math Operations
        case (
            ir.Sin()
            | ir.Cos()
            | ir.Log()
            | ir.Sqrt()
            | ir.Exp()
            | ir.Sinh()
            | ir.Cosh()
            | ir.Tanh()
        ) as op:
            op_name = type(op).__name__.lower()
            return f"math.{op_name} {lookup_fn(op.operand)} : f32"
        case ir.Neg(operand=op):
            return f"arith.negf {lookup_fn(op)} : f32"

        # Type Casting
        case ir.CastF32(operand=op):
            return f"arith.sitofp {lookup_fn(op)} : i64 to f32"
        case ir.CastI64(operand=op):
            return f"arith.fptosi {lookup_fn(op)} : f32 to i64"

        case _:
            raise NotImplementedError(f"Unsupported expression type: {type(expr)}")
MLIR 백엔드 (mlir_backend.py)
컴파일러의 MLIR 백엔드는 고수준 MLIR 코드를 여러 로어링 단계를 거쳐 변환하여 LLVM IR에 도달하게 하고, 최종적으로 실행 가능한 코드로 만드는 역할을 합니다. 핵심 구성 요소와 설계 원칙을 차례로 살펴봅시다:
백엔드는 두 가지 주요 컴파일 대상을 지원합니다:
class Target(enum.Enum):
    OPENMP = "openmp"      # Parallel execution using OpenMP
    BASIC_LOOPS = "loops"  # Sequential execution with basic loops
이를 통해 컴파일러는 애플리케이션의 요구에 따라 멀티스레드 실행을 위해 OpenMP를 사용하는 병렬 코드를 생성하거나, 더 단순한 순차 코드를 생성할 수 있습니다.
컴파일 과정은 여러 개의 뚜렷한 단계로 구성되며, 각 단계는 특정 MLIR 최적화 패스를 적용합니다:
-
공통 초기 변환:
COMMON_INITIAL_OPTIONS = (
    "--debugify-level=locations",
    "--inline",
    "-affine-loop-normalize",
    "-affine-parallelize",
    "-affine-super-vectorize",
    "--affine-scalrep",
    "-lower-affine",
    "-convert-vector-to-scf",
    "-convert-linalg-to-loops",
)
이 패스들은 함수 인라이닝, 루프 정규화, 벡터화, 초기 다이얼렉트 변환을 처리합니다.
-
대상별 로어링:
- OpenMP 경로: 구조적 제어 흐름을 OpenMP 연산으로 변환한 다음 LLVM으로 변환합니다
OPENMP_OPTIONS = ( "-convert-scf-to-openmp", "-convert-openmp-to-llvm", "-convert-vector-to-llvm", "-convert-math-to-llvm", # ... additional lowering passes )- 기본 루프 경로: 순차 LLVM IR로 직접 변환합니다
BASIC_LOOPS_OPTIONS = ( "-convert-scf-to-cf", "-convert-vector-to-llvm", "-convert-math-to-llvm", # ... additional lowering passes ) -
최종 LLVM IR 생성:
MLIR_TRANSLATE_OPTIONS = (
    "--mlir-print-local-scope",
    "--mlir-to-llvmir",
    "--verify-diagnostics",
)
MLIRCompiler 클래스는 세 가지 주요 단계를 통해 전체 컴파일 과정을 조율합니다:
-
MLIR에서 LLVM 다이얼렉트로 (
to_llvm_dialect):- 고수준 MLIR 연산을 LLVM 다이얼렉트로 변환합니다
- 대상별 최적화(OpenMP 또는 기본 루프)를 적용합니다
- 메모리 레이아웃과 타입 변환을 처리합니다
-
LLVM 다이얼렉트에서 LLVM IR로 (
mlir_translate_to_llvm_ir):- LLVM 다이얼렉트 표현을 텍스트 형식의 LLVM IR로 변환합니다
- 디버그 정보를 보존하고 생성된 코드를 검증합니다
-
LLVM IR에서 비트코드로 (
llvm_ir_to_bitcode):- 텍스트 형식의 LLVM IR을 바이너리 LLVM 비트코드로 변환합니다
- 최종 실행을 위해 코드를 준비합니다
백엔드는 중간 표현에 임시 파일을 사용하며, debug 플래그를 통해 디버깅 기능을 제공합니다:
def _run_shell(self, cmd, in_mode, out_mode, src):
    with (
        NamedTemporaryFile(mode=f"w{in_mode}") as src_file,
        NamedTemporaryFile(mode=f"r{out_mode}") as out_file,
    ):
        # Execute compilation command and handle I/O
그러면 컴파일러가 LLVM IR을 내놓고, 우리는 llvmlite 라이브러리를 사용해 이를 Python 프로세스 안에서 로드하고 실행할 수 있으므로, 컴파일된 기계어 코드를 동적으로 로드할 수 있습니다.
LLVM 런타임 (llvm_runtime.py)
LLVM 런타임은 컴파일 파이프라인의 마지막 계층으로, 컴파일된 LLVM 코드를 Python 안에서 동적으로 로드하고 실행하는 일을 담당합니다. 이 구성 요소는 llvmlite를 사용해 LLVM과 연동하며 JIT(Just-In-Time) 컴파일 과정을 관리합니다.
LLVM 초기화
런타임은 LLVM 구성 요소의 캐시된 초기화로 시작합니다:
@cache
def init_llvm():
    llvm.initialize()
    llvm.initialize_all_targets()
    llvm.initialize_all_asmprinters()
이 초기화는 Python 세션당 한 번만 실행되도록 캐시되며, LLVM Core 기능, 사용 가능한 모든 대상 아키텍처, 그리고 코드 생성에 필요한 어셈블리 프린터를 설정합니다.
런타임은 JIT 컴파일 과정을 관리하는 LLVM 실행 엔진을 생성합니다:
def create_execution_engine():
    target = llvm.Target.from_default_triple()
    target_machine = target.create_target_machine()
    backing_mod = llvm.parse_assembly("")
    engine = llvm.create_mcjit_compiler(backing_mod, target_machine)
    return engine
이 설정은 호스트 머신의 대상 아키텍처를 파악하고, 코드 생성을 위한 대상 머신 인스턴스를 만들고, 백킹 스토어로 사용할 빈 LLVM 모듈을 초기화하며, 최적화된 코드 실행을 위한 MCJIT 컴파일러 인스턴스를 생성합니다.
런타임은 두 가지 수준의 모듈 컴파일을 제공합니다:
- 직접 모듈 컴파일:
def compile_mod(engine, mod):
    mod.verify()                     # Verify module correctness
    engine.add_module(mod)           # Add to execution engine
    engine.finalize_object()         # Finalize compilation
    engine.run_static_constructors() # Initialize static data
    return mod
- IR 문자열 컴파일:
def compile_ir(engine, llvm_ir):
    mod = llvm.parse_assembly(llvm_ir)  # Parse IR text
    return compile_mod(engine, mod)      # Compile module
이 런타임 계층은 LLVM의 저수준 컴파일 인프라와 Python의 고수준 실행 환경 사이의 간극을 메워, 컴파일된 커널이 Python 프로세스 안에서 효율적으로 실행될 수 있게 합니다.
import llvmlite.binding as llvm
import llvmlite
from functools import cache


@cache
def init_llvm():
    print(llvmlite.__version__)
    llvm.initialize()
    llvm.initialize_all_targets()
    llvm.initialize_all_asmprinters()


def compile_mod(engine, mod):
    mod.verify()
    engine.add_module(mod)
    engine.finalize_object()
    engine.run_static_constructors()
    return mod


def create_execution_engine():
    target = llvm.Target.from_default_triple()
    target_machine = target.create_target_machine()
    backing_mod = llvm.parse_assembly("")
    engine = llvm.create_mcjit_compiler(backing_mod, target_machine)
    return engine


def compile_ir(engine, llvm_ir):
    mod = llvm.parse_assembly(llvm_ir)
    return compile_mod(engine, mod)
JIT 엔진 (jit_engine.py)
jit_engine.py 모듈은 컴파일러 파이프라인을 총괄하며, 모든 구성 요소를 하나로 엮어 매끄러운 컴파일 과정을 만들어 냅니다. 이 모듈은 Python 함수에서 실행 가능한 기계어 코드에 이르는 전체 생명주기를 관리하며, 최적화, 코드 생성, 런타임 실행을 처리합니다.
JITEngine 클래스는 세 가지 주요 수준의 컴파일을 제공합니다:
-
프런트엔드 컴파일 (
run_frontend):def run_frontend( self, fn: FunctionType, rewrites: tuple[RewriteOrRule | Ruleset, ...] | None = None, ) -> str:run_frontend메서드는 Python 함수와 선택적인 재작성 규칙을 받아, egglog 최적화기를 적용해 항 재작성을 수행하고, 최적화된 MLIR 코드를 생성합니다. -
백엔드 컴파일 (
run_backend):def run_backend(self, mlir_src: str) -> bytes: mlir_compiler = MLIRCompiler(debug=False) mlir_omp = mlir_compiler.to_llvm_dialect(mlir_src) llvm_ir = mlir_compiler.mlir_translate_to_llvm_ir(mlir_omp)run_backend메서드는 MLIR을 LLVM 다이얼렉트로 변환하고, 이를 LLVM IR로 번역하며, 플랫폼별 최적화를 처리한 뒤, 최종적으로 컴파일된 함수의 주소를 반환합니다. -
전체 JIT 컴파일 (
jit_compile):def jit_compile( self, fn: FunctionType, rewrites: tuple[RewriteOrRule | Ruleset, ...] | None = None, ) -> bytes: mlir = self.run_frontend(fn, rewrites) address = self.run_backend(mlir) return addressjit_compile메서드는 프런트엔드 컴파일과 백엔드 컴파일을 결합하여, 전체 컴파일 과정을 위한 단일 진입점을 제공합니다.
OpenMP 런타임을 사용하려면 시스템별 OpenMP 라이브러리를 Python 프로세스에 로드해야 합니다. 공유 라이브러리의 올바른 경로를 알고 나면 ctypes 라이브러리를 통해 이를 수행할 수 있습니다.
def find_omp_path():
if sys.platform.startswith("linux"):
omppath = ctypes.util.find_library("libgomp.so")
elif sys.platform.startswith("darwin"):
omppath = ctypes.util.find_library("iomp5")
else:
raise RuntimeError(f"Unsupported platform: {sys.platform}")
return omppath
엔진은 LLVM과 관련된 몇 가지 중요한 작업을 처리합니다.
-
초기화:
def __init__(self): init_llvm() omppath = find_omp_path() ctypes.CDLL(omppath, mode=os.RTLD_NOW) self.ee = create_execution_engine()- LLVM 인프라를 초기화합니다
- OpenMP 런타임을 로드합니다
- 실행 엔진을 생성합니다
이 클래스는 컴파일러의 구성 요소들을 하나로 묶는 접착제 역할을 하며, Python 코드와 최적화된 기계어 코드 실행 사이의 인터페이스를 제공합니다. 이 클래스는 다단계 컴파일, 플랫폼별 요구 사항, 런타임 최적화의 복잡성을 처리합니다.
from __future__ import annotations
import ctypes
import ctypes.util
import os
import sys
from types import FunctionType
from egglog import RewriteOrRule, Ruleset
import llvmlite.binding as llvm
from mlir_egglog.llvm_runtime import (
create_execution_engine,
init_llvm,
compile_mod,
)
from mlir_egglog.mlir_gen import KERNEL_NAME
from mlir_egglog.mlir_backend import MLIRCompiler, Target
from mlir_egglog.egglog_optimizer import compile, OPTS
def find_omp_path():
if sys.platform.startswith("linux"):
omppath = ctypes.util.find_library("libgomp.so")
elif sys.platform.startswith("darwin"):
omppath = ctypes.util.find_library("iomp5")
else:
raise RuntimeError(f"Unsupported platform: {sys.platform}")
return omppath
class JITEngine:
def __init__(self):
init_llvm()
omppath = find_omp_path()
ctypes.CDLL(omppath, mode=os.RTLD_NOW)
self.ee = create_execution_engine()
def run_frontend(
    self,
    fn: FunctionType,
    rewrites: tuple[RewriteOrRule | Ruleset, ...] | None = None,
) -> str:
actual_rewrites = rewrites if rewrites is not None else OPTS
return compile(fn, rewrites=actual_rewrites, debug=False)
def run_backend(self, mlir_src: str) -> bytes:
mlir_compiler = MLIRCompiler(debug=False)
mlir_omp = mlir_compiler.to_llvm_dialect(mlir_src, target=Target.BASIC_LOOPS)
llvm_ir = mlir_compiler.mlir_translate_to_llvm_ir(mlir_omp)
print(llvm_ir)
print("Parsing LLVM assembly.")
try:
# Clean up the LLVM IR by ensuring proper line endings and formatting
llvm_ir = llvm_ir.strip()
# Clean up problematic attribute strings (hack for divergence in modern LLVM IR syntax with old llvmlite)
llvm_ir = llvm_ir.replace("captures(none)", " ")
llvm_ir = llvm_ir.replace("memory(argmem: readwrite)", "")
llvm_ir = llvm_ir.replace("memory(none)", "")
llvm_ir += "\n"
mod = llvm.parse_assembly(llvm_ir)
mod = compile_mod(self.ee, mod)
# Resolve the function address
func_name = f"_mlir_ciface_{KERNEL_NAME}"
address = self.ee.get_function_address(func_name)
assert address, "Function must be compiled successfully."
return address
except Exception as e:
print(f"Error during LLVM IR parsing/compilation: {str(e)}")
print("LLVM IR that failed to parse:")
print(llvm_ir)
raise
def jit_compile(
    self,
    fn: FunctionType,
    rewrites: tuple[RewriteOrRule | Ruleset, ...] | None = None,
) -> bytes:
    mlir = self.run_frontend(fn, rewrites)
    address = self.run_backend(mlir)
    return address
디스패처 (dispatcher.py)
디스패처는 컴파일러의 사용자 대면 인터페이스 역할을 하며, 일반 Python 함수를 최적화된 벡터화 커널로 변환하는 데코레이터를 제공합니다. 디스패처는 컴파일 과정을 처리하고 컴파일된 함수의 실행을 관리합니다.
Dispatcher 클래스는 컴파일된 함수의 생명 주기를 관리합니다.
class Dispatcher:
    _compiled_func: bytes | None      # Compiled function address
    _compiler: JITEngine | None       # JIT compilation engine
    py_func: types.FunctionType       # Original Python function
    rewrites: tuple[RewriteOrRule, ...] | None  # Optimization rules
컴파일 과정은 컴파일러의 jit_compile 메서드를 호출하는 간단한 인터페이스를 통해 처리됩니다.
def compile(self):
    self._compiler = JITEngine()
    binary = self._compiler.jit_compile(self.py_func, self.rewrites)
    self._compiled_func = binary
    return binary
이 메서드는 새 JIT 엔진 인스턴스를 생성하고, 지정된 재작성 규칙으로 Python 함수를 컴파일한 뒤, 이후 실행을 위해 컴파일된 바이너리를 저장합니다. 디스패처는 이후 호출 시 함수를 다시 컴파일하지 않도록 캐시된 호출 메커니즘을 구현합니다. 컴파일된 함수를 numpy 배열과 함께 호출하면 디스패처는 기저 입력 배열을 가져오고 같은 형태의 새 빈 출력 배열을 할당합니다. 그런 다음 numpy 배열을 memref 디스크립터로 변환하여 컴파일된 함수에 전달합니다.
def __call__(self, *args, **kwargs):
    # Get the input array and its shape
    input_array = args[0]
    original_shape = input_array.shape

    # Flatten the input array
    flattened_input = input_array.flatten()
    flattened_output = np.empty_like(flattened_input)

    # Convert to memrefs
    memrefs = [
        as_memref_descriptor(flattened_input, ctypes.c_float),
        as_memref_descriptor(flattened_output, ctypes.c_float)
    ]
그런 다음 디스패처는 MCJIT로 컴파일된 메모리에서 함수 포인터를 조회하고, memref 디스크립터를 인자로 하여 이를 호출합니다.
# Create function prototype for ctypes
prototype = ctypes.CFUNCTYPE(None, *[ctypes.POINTER(type(x)) for x in memrefs])

# Execute compiled function
cfunc = prototype(self._compiled_func)
cfunc(*[ctypes.byref(x) for x in memrefs])
이제 컴파일러로 함수를 컴파일하려면 우리가 작성한 함수에 @kernel 데코레이터를 사용하면 됩니다.
import llvmlite
import numpy as np
llvmlite.opaque_pointers_enabled = True

from mlir_egglog import kernel

@kernel("float32(float32)")
def fn(a):
    return np.sin(a) * np.cos(a) + np.cos(a) * np.sin(a)

out = fn(np.array([1.0], dtype=np.float32))
print(out)
이것은 매우 단순한 예제 컴파일러입니다. 기호적 해석 방식은 제어 흐름 연산이 없는 평탄한 함수만 처리할 수 있고, 인자 타입을 직접 지정해야 하며, 제한된 연산 집합만 지원하므로 근본적인 한계가 있습니다. 하지만 MLIR과 e-그래프를 최적화에 활용하여 처음부터 끝까지 동작하는 무언가를 살펴보기에는 좋은 출발점입니다.
7부에서는 GPT-2의 NumPy 참조 구현을 만들어 보겠습니다. 이를 통해 컴파일러를 이러한 원소별 표현식 너머로 확장할 때 목표로 삼을 구체적인 텐서 연산 집합을 얻게 됩니다.
외부 자료
- Equality Saturation: A New Approach to Optimization
- E-graphs for Efficient Symbolic Compilation with Egglog
- egglog Tutorial (EGRAPHS 2023) | Next Generation Egraphs
- DPopt: Differentiable Placement Optimization for Hardware Acceleration
- Equality Saturation for MLIR with Egglog
- Guided Equality Saturation
- SEER: Super-Optimization Explorer for High-Level Synthesis using E-graph Rewriting
- 동치 포화
- Egglog로 구현하는 SK 논리 (1)
- PEG: 프로그램 분석과 동적 프로그래밍의 결합
- RelBench: 관계형 학습을 위한 통합 벤치마크
- Egraph-CHR
- DialEgg: Egglog 기반 동치 포화를 사용하는 다이얼렉트 비의존적 MLIR 최적화기
- Egglog 체크포인트
- egg를 이용한 빠르고 확장 가능한 동치 포화
- 동치 포화의 이론적 측면 (1부)
- 동치 포화: 최적화에 대한 새로운 접근법 (YouTube)
- 동치 포화: 항 추출과 네트워크 합성에의 응용
- Egglog (동치 포화를 위한) - Portland State 검증 세미나
- 동치 포화를 이용한 엔드투엔드 컴파일
- Egglog (동치 포화를 위한) - PLDI 발표
- Ask HN: 컴파일러 분야에서 진행 중인 흥미로운 연구나 프로젝트는 무엇입니까?