MLIR의 선형대수
Linalg 다이얼렉트는 MLIR 생태계의 핵심(Core) 아이디어로, 고수준 텐서 연산을 더 쉽고 효율적으로 만들기 위해 만들어졌습니다. 본질적으로 이 다이얼렉트의 목적은 복잡한 수학 연산을 다루는 방식을 단순화하여, 빠르고 최적화된 코드로 변환할 수 있게 하는 데 있습니다. 근본적으로(Core) Linalg 다이얼렉트는 단순하고 선언적인 접근 방식을 사용합니다. 즉, 수학적 의미를 그대로 유지하면서도 다양한 최적화가 가능하도록 연산과 변환을 표현합니다. 점별(pointwise) 계산, 행렬 곱셈, 합성곱과 같은 고수준 선형대수 연산을 단일 연산으로 제공합니다.
linalg.generic
Linalg 다이얼렉트에서 가장 일반적인 연산은 linalg.generic입니다. 이 연산을 사용하면 인덱스에 대한 일반적인 텐서 조작 연산을 정의할 수 있습니다. 이것은 가장 일반적인 연산이며, 다른 모든 연산은 이 연산의 특수화로 정의됩니다. 이 연산을 직접 사용할 일은 많지 않겠지만, 가장 기본이 되는 연산이므로 먼저 살펴보는 것이 유용합니다.
#map_1d_identity = affine_map<(d0) -> (d0)>

func.func @add_tensors(%arg0: tensor<10xf32>, %arg1: tensor<10xf32>) -> tensor<10xf32> {
  %result = tensor.empty() : tensor<10xf32>
  %0 = linalg.generic {
    // attributes
      indexing_maps = [
        #map_1d_identity,
        #map_1d_identity,
        #map_1d_identity
       ],
      iterator_types = [
        "parallel"
      ]
    }
    // input tensors
    ins(%arg0, %arg1 : tensor<10xf32>, tensor<10xf32>)
    // output tensor
    outs(%result : tensor<10xf32>)
    // loop region
    {
    ^bb0(%arg2: f32, %arg3: f32, %arg4: f32):
      %1 = arith.addf %arg2, %arg3 : f32
      linalg.yield %1 : f32
    } -> tensor<10xf32>
  return %0 : tensor<10xf32>
}
이 linalg.generic 연산의 각 구성 요소를 하나씩 살펴봅시다.
-
indexing_maps: 이 속성은 입력 텐서와 출력 텐서에 접근하는 방식을 정의합니다. 여기에는 3개의 맵이 있습니다.- 첫 번째 입력 텐서(
%arg0)를 위한 첫 번째 맵 - 두 번째 입력 텐서(
%arg1)를 위한 두 번째 맵 - 출력 텐서(
%result)를 위한 세 번째 맵
모두
affine_map<(d0) -> (d0)>로 정의된#map_1d_identity를 사용하며, 이는 각 원소가 대응하는 원소에 직접 매핑된다는 뜻입니다(좌표 변환 없음). - 첫 번째 입력 텐서(
-
iterator_types: 각 차원의 반복 유형을 지정합니다. 여기에는 다음이 있습니다.["parallel"]: 단일 차원이 parallel로 표시되어 있으며, 이는 반복을 임의의 순서로 또는 동시에 실행할 수 있다는 뜻입니다.
linalg에는 세 가지 반복자 유형이 있습니다.
parallel: 반복을 임의의 순서로 또는 동시에 실행할 수 있습니다(원소별 연산 등)reduction: 반복이 하나의 결과 값에 기여합니다(축을 따라 합산하는 경우 등)window: 반복이 원소의 슬라이딩 윈도우에 접근합니다(합성곱 등)
-
ins(%arg0, %arg1 : tensor<10xf32>, tensor<10xf32>):- 입력 텐서와 그 타입을 지정합니다
- 둘 다 float32 원소 10개로 이루어진 1차원 텐서입니다
-
outs(%result : tensor<10xf32>):- 출력 텐서와 그 타입을 지정합니다
- 마찬가지로 float32 원소 10개로 이루어진 1차원 텐서입니다
-
영역(루프 본문):
{ ^bb0(%arg2: f32, %arg3: f32, %arg4: f32): %1 = arith.addf %arg2, %arg3 : f32 linalg.yield %1 : f32 }- 입력 텐서(%arg2, %arg3)와 출력 텐서(%arg4)에서 스칼라 값을 가져옵니다
- 부동소수점 덧셈을 수행합니다
linalg.yield를 사용해 결과를 반환합니다
이 연산은 NumPy에서와 마찬가지로 두 텐서를 원소별로 더하는 표준 벡터화 덧셈을 수행합니다:
np.array([1,2,3]) + np.array([2,3,4])
# array([3, 5, 7])
내용이 많아 보이더라도 걱정하지 마십시오. 실제로 많습니다. 같은 결과로 컴파일되면서 훨씬 더 간단하게 작성하는 방법이 있습니다.
linalg.map
같은 연산을 범용 linalg.map 연산으로도 작성할 수 있습니다. 이 연산은 루프 중첩과 인덱스 조작의 세부 사항을 추상화하고, 그 대신 arith.addf 연산을 입력 텐서에 직접 적용합니다.
module {
  func.func @addv(%arg0: tensor<10xf32>, %arg1: tensor<10xf32>, %out: memref<10xf32>) {
    %out2 = tensor.empty() : tensor<10xf32>
    %result = linalg.map { arith.addf } ins(%arg0, %arg1 : tensor<10xf32>, tensor<10xf32>) outs(%out2 : tensor<10xf32>)

    %l = bufferization.to_memref %result : tensor<10xf32> to memref<10xf32>
    memref.copy %l, %out : memref<10xf32> to memref<10xf32>

    return
  }
}
자주 쓰이는 산술 맵 연산에는 이름이 붙은 연산도 있습니다. 이들은 linalg.map 연산을 특수화하여 이름을 붙인 것입니다.
linalg.addlinalg.mullinalg.divlinalg.sub
linalg.reduce
linalg.reduce 연산은 다양한 리덕션 연산을 구현하는 데 사용할 수 있는 강력한 기본 연산입니다.
func.func @add_tensor() -> (f64) {
  %_ssa_0 = tensor.empty () : tensor<3xf64>
  %out = tensor.empty () : tensor<f64>
  %reduce = linalg.reduce { arith.addf } ins(%_ssa_0:tensor<3xf64>) outs(%out:tensor<f64>) dimensions = [0]
  %result = tensor.extract %reduce [] : tensor<f64>
  return %result : f64
}
NumPy에서는 이 연산을 다음과 같이 작성할 수 있습니다:
import numpy as np
np.multiply.reduce([2,3,5]) # 30
linalg.matmul
직접적인 텐서 축약을 이용하여 범용 행렬 곱셈 연산을 정의할 수도 있습니다. MLIR 코드에 나온 행렬 곱셈 연산은 일반적인 텐서 표기법으로 다음과 같이 쓸 수 있습니다:
여기서:
- 는 8×10 입력 행렬(
memref<8x10xf32>)입니다 - 는 10×16 입력 행렬(
memref<10x16xf32>)입니다 - 는 8×16 출력 행렬(
memref<8x16xf32>)입니다 - 는 1부터 8까지의 범위를 가집니다
- 는 1부터 16까지의 범위를 가집니다
- 는 1부터 10까지의 범위를 가지는 합산 인덱스입니다
이는 다음과 같은 MLIR 구현과 일치합니다:
parallel반복자 타입은 자유 인덱스 와 에 대응합니다reduction반복자 타입은 에 대한 합산에 대응합니다- 인덱싱 맵
(i, j, k) -> (i, k),(i, j, k) -> (k, j),(i, j, k) -> (i, j)는 각각 , , 에 대한 접근에 대응합니다
func.func @matmul(
    %A: memref<8x10xf32>,
    %B: memref<10x16xf32>,
    %C: memref<8x16xf32>
) {
    linalg.generic {
        indexing_maps = [
            affine_map<(i, j, k) -> (i, k)>,
            affine_map<(i, j, k) -> (k, j)>,
            affine_map<(i, j, k) -> (i, j)>
        ],
        iterator_types = [
            "parallel",
            "parallel",
            "reduction"
        ]
    } ins(%A, %B : memref<8x10xf32>, memref<10x16xf32>) outs(%C : memref<8x16xf32>) {
        ^bb0(%lhs_one: f32, %rhs_one: f32, %init_one: f32):
            %tmp0 = arith.mulf %lhs_one, %rhs_one : f32
            %tmp1 = arith.addf %init_one, %tmp0 : f32
            linalg.yield %tmp1 : f32
    }
    return
}
또는 linalg.matmul 연산을 사용하면 훨씬 더 간결하게 작성할 수 있습니다.
func.func @matmul(
    %A: memref<8x10xf32>,
    %B: memref<10x16xf32>,
    %C: memref<8x16xf32>
) {
    linalg.matmul ins(%A, %B : memref<8x10xf32>, memref<10x16xf32>) outs(%C : memref<8x16xf32>)
    return
}
그런 다음 convert-linalg-to-loops 또는 convert-linalg-to-affine-loops 패스를 사용하여 텐서 연산을 affine.for 또는 scf.for 연산으로 이루어진 루프 시퀀스로 로워링합니다.
func.func @matmul(%arg0: memref<8x10xf32>, %arg1: memref<10x16xf32>, %arg2: memref<8x16xf32>) {
  affine.for %arg3 = 0 to 8 {
    affine.for %arg4 = 0 to 16 {
      affine.for %arg5 = 0 to 10 {
        %0 = affine.load %arg0[%arg3, %arg5] : memref<8x10xf32>
        %1 = affine.load %arg1[%arg5, %arg4] : memref<10x16xf32>
        %2 = affine.load %arg2[%arg3, %arg4] : memref<8x16xf32>
        %3 = arith.mulf %0, %1 : f32
        %4 = arith.addf %2, %3 : f32
        affine.store %4, %arg2[%arg3, %arg4] : memref<8x16xf32>
      }
    }
  }
  return
}
func.func @matmul(%arg0: memref<8x10xf32>, %arg1: memref<10x16xf32>, %arg2: memref<8x16xf32>) {
  %c0 = arith.constant 0 : index
  %c8 = arith.constant 8 : index
  %c1 = arith.constant 1 : index
  %c16 = arith.constant 16 : index
  %c10 = arith.constant 10 : index
  scf.for %arg3 = %c0 to %c8 step %c1 {
    scf.for %arg4 = %c0 to %c16 step %c1 {
      scf.for %arg5 = %c0 to %c10 step %c1 {
        %0 = memref.load %arg0[%arg3, %arg5] : memref<8x10xf32>
        %1 = memref.load %arg1[%arg5, %arg4] : memref<10x16xf32>
        %2 = memref.load %arg2[%arg3, %arg4] : memref<8x16xf32>
        %3 = arith.mulf %0, %1 : f32
        %4 = arith.addf %2, %3 : f32
        memref.store %4, %arg2[%arg3, %arg4] : memref<8x16xf32>
      }
    }
  }
  return
}
브로드캐스팅
MLIR의 Linalg 다이얼렉트에서 브로드캐스팅을 사용하면 NumPy의 브로드캐스팅 규칙과 비슷하게 서로 다른 형태의 텐서를 하나의 연산에서 결합할 수 있습니다. 브로드캐스트 차원을 따라 더 작은 텐서가 더 큰 텐서의 형태에 맞도록 암묵적으로 확장됩니다. 이는 행렬의 각 행/열에 벡터를 더하거나 텐서에 스칼라 연산을 적용하는 것과 같은 연산에서 특히 유용합니다.
몇 가지 일반적인 브로드캐스팅 패턴을 살펴봅시다.
func.func @broadcast_1d_to_2d(%arg0: tensor<3xf32>) -> tensor<3x3xf32> {
  // Create an empty output tensor
  %init = tensor.empty() : tensor<3x3xf32>

  // Broadcast the input tensor along dimension 1 (columns)
  %result = linalg.broadcast
    ins(%arg0: tensor<3xf32>)
    outs(%init: tensor<3x3xf32>)
    dimensions = [1]

  return %result : tensor<3x3xf32>
}
NumPy에서는 이 연산을 다음과 같이 작성할 수 있습니다.
arg0 = np.array([1,2,3])
result = np.broadcast_to(arg0, (3,3))
# array([[1, 2, 3],
#        [1, 2, 3],
#        [1, 2, 3]])
브로드캐스팅을 다른 연산과 결합할 수도 있습니다. 예를 들어, 행렬의 각 행에 벡터를 더하는 연산은 다음과 같습니다.
func.func @add_vector_to_matrix(
    %matrix: tensor<3x4xf32>,
    %vector: tensor<4xf32>
) -> tensor<3x4xf32> {
  %init = tensor.empty() : tensor<3x4xf32>

  // First broadcast the vector
  %broadcasted = linalg.broadcast
    ins(%vector: tensor<4xf32>)
    outs(%init: tensor<3x4xf32>)
    dimensions = [0]

  // Then add the broadcasted result to the matrix
  %result = linalg.map { arith.addf }
    ins(%matrix, %broadcasted: tensor<3x4xf32>, tensor<3x4xf32>)
    outs(%init: tensor<3x4xf32>)

  return %result : tensor<3x4xf32>
}
이는 흔히 쓰이는 다음 NumPy 연산과 동일합니다.
matrix = np.ones((3,4))
vector = np.array([1,2,3,4])
result = matrix + vector
# array([[2., 3., 4., 5.],
#        [2., 3., 4., 5.],
#        [2., 3., 4., 5.]])
커널 융합
커널 융합은 여러 연산을 하나의 연산으로 결합하여 메모리 대역폭 요구량을 줄이고 성능을 향상시키는 중요한 최적화 기법입니다. Linalg 다이얼렉트는 최적화 패스를 통해 원소별 연산의 융합을 기본적으로 지원합니다.
덧셈 다음에 곱셈이 오는 두 연산을 하나로 융합하려는 간단한 예제를 살펴봅시다. 먼저 이 연산들을 별개의 연산으로 작성하겠습니다.
module {
  func.func @addmul(%arg0: tensor<10xf32>, %arg1: tensor<10xf32>, %arg2: tensor<10xf32>) -> tensor<10xf32> {
    // First create an empty tensor for intermediate results
    %0 = tensor.empty() : tensor<10xf32>

    // Add operation
    %1 = linalg.add ins(%arg0, %arg1 : tensor<10xf32>, tensor<10xf32>)
                    outs(%0 : tensor<10xf32>) -> tensor<10xf32>

    // Create another empty tensor for the multiplication result
    %2 = tensor.empty() : tensor<10xf32>

    // Multiply operation
    %3 = linalg.mul ins(%1, %arg2 : tensor<10xf32>, tensor<10xf32>)
                    outs(%2 : tensor<10xf32>) -> tensor<10xf32>

    return %3 : tensor<10xf32>
  }
}
여기에는 linalg.add 다음에 linalg.mul이 오는 두 개의 별개 연산이 있습니다. 각 연산마다 메모리에서 읽고 다시 메모리에 써야 하므로 비효율적일 수 있습니다.
MLIR의 최적화 패스를 통해 이 연산들을 데이터를 한 번만 순회하면서 두 연산을 모두 수행하는 단일 커널로 융합할 수 있습니다.
#map = affine_map<(d0) -> (d0)>
module {
  func.func @addmul(%arg0: tensor<10xf32>, %arg1: tensor<10xf32>, %arg2: tensor<10xf32>) -> tensor<10xf32> {
    %0 = tensor.empty() : tensor<10xf32>
    %1 = linalg.generic {indexing_maps = [#map, #map, #map, #map],
        iterator_types = ["parallel"]} ins(%arg0, %arg1, %arg2 : tensor<10xf32>,
        tensor<10xf32>, tensor<10xf32>) outs(%0 : tensor<10xf32>) {
    ^bb0(%in: f32, %in_0: f32, %in_1: f32, %out: f32):
      %2 = arith.addf %in, %in_0 : f32
      %3 = arith.mulf %2, %in_1 : f32
      linalg.yield %3 : f32
    } -> tensor<10xf32>
    return %1 : tensor<10xf32>
  }
}
이것이 어떻게 동작하는지 감을 잡기 위해 동등한 Python 코드를 살펴봅시다.
# Unfused version - two separate loops
def unfused_addmul(a, b, c):
    # First loop - addition
    temp = []
    for i in range(len(a)):
        temp.append(a[i] + b[i])

    # Second loop - multiplication
    result = []
    for i in range(len(temp)):
        result.append(temp[i] * c[i])

    return result

# Fused version - single loop
def fused_addmul(a, b, c):
    result = []
    for i in range(len(a)):
        # Combine add and multiply in one loop iteration
        result.append((a[i] + b[i]) * c[i])
    return result

a = [1.0, 2.0, 3.0, 4.0, 5.0]
b = [1.0, 1.0, 1.0, 1.0, 1.0]
c = [2.0, 2.0, 2.0, 2.0, 2.0]

# Both produce same result but fused version only loops once
result = fused_addmul(a, b, c)  # [(1+1)*2, (2+1)*2, (3+1)*2, ...]
융합된 버전은 두 연산을 하나의 linalg.generic 연산으로 결합하며, 이 연산은 각 입력을 한 번만 읽고 최종 결과를 바로 씁니다. 이렇게 하면 중간 텐서 할당과 그에 따른 메모리 접근이 사라집니다.
이 융합을 수행하려면 특정한 순서로 최적화 패스를 적용해야 합니다.
--canonicalize: 전반적인 정리와 단순화를 수행합니다--linalg-fuse-elementwise-ops: 원소별 연산을 융합합니다--cse: 공통 하위 표현식 제거(Common Subexpression Elimination)로 중복 연산을 정리합니다--linalg-generalize-named-ops: 이름 있는 연산(linalg.add등)을 generic 형태로 변환합니다--convert-linalg-to-loops: 융합된 연산을 명시적인 루프로 변환합니다
이 패스들을 실행하여 융합된 addmul 연산을 fused_ops.mlir에 출력할 수 있으며, 이로써 에 대한 두 개의 루프가 에 대한 하나의 루프로 줄어들어 시간 복잡도가 감소합니다.
mlir-opt separate_ops.mlir \
  --canonicalize \
  --linalg-fuse-elementwise-ops \
  --cse \
  --linalg-generalize-named-ops \
  --linalg-fuse-elementwise-ops \
  --convert-linalg-to-loops \
  -o fused_ops.mlir
이 패스 순서를 따르면 연산이 올바르게 융합된 다음 효율적으로 실행할 수 있는 형태로 하강(lowering)됩니다. 융합 최적화는 원소별 연산이 연쇄적으로 이어지는 경우가 많은 딥러닝 워크로드에서 특히 중요합니다.
타일링
루프 타일링은 메모리 접근 패턴과 캐시 활용도를 개선하는 핵심 최적화 기법입니다. 현대 컴퓨터 아키텍처에서는 연산보다 메모리 접근이 병목이 되는 경우가 많습니다. 큰 행렬이나 텐서를 처리할 때 메모리에 선형적으로 접근하면 캐시 메모리보다 훨씬 느린 주 메모리에서 새 데이터를 계속 가져와야 할 수 있습니다.
타일링은 큰 연산을 캐시 메모리에 더 잘 들어맞는 작은 블록으로 나눕니다. 예를 들어 행렬 곱셈에서는 행과 열의 내적 전체를 한 번에 계산하는 대신(캐시 크기를 초과할 수 있으므로) 캐시 메모리에 상주할 수 있는 작은 타일로 나눕니다. 이렇게 하면 캐시 미스가 줄고 성능이 향상됩니다.
이 최적화는 메모리 계층 구조와 접근 패턴이 성능에 큰 영향을 미치는 GPU 아키텍처에서 특히 중요합니다. GPU에는 전역 메모리, 공유 메모리(캐시와 유사함), 레지스터를 포함하는 복잡한 메모리 계층 구조가 있습니다. 공유 메모리 크기나 워프 크기 같은 GPU의 하드웨어 특성에 맞춰 연산을 타일링하면 성능을 극적으로 향상시킬 수 있습니다. 예를 들어 CUDA 프로그래밍에서 흔히 쓰이는 패턴은 데이터 타일 하나를 공유 메모리에 로드하고, 스레드를 동기화한 다음, 각 스레드가 그 타일 안의 원소를 처리하게 하는 것입니다. 이에 대해서는 뒤의 GPU 프로그래밍 절에서 더 자세히 다룹니다.
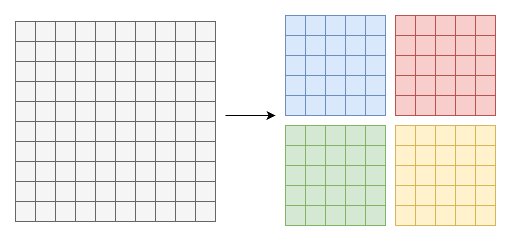
다음은 MLIR을 사용하여 행렬 곱셈 연산에 루프 타일링을 수행하는 예제입니다. 간단한 텐서 기반 matmul에서 시작하여 이를 타일링된 affine 루프로 변환하겠습니다.
module {
  func.func @matmul(%arg0: tensor<10x10xf32>, %arg1: tensor<10x10xf32>,
                    %arg2: tensor<10x10xf32>) -> tensor<10x10xf32> {
    %0 = linalg.matmul
           ins(%arg0, %arg1 : tensor<10x10xf32>, tensor<10x10xf32>)
           outs(%arg2 : tensor<10x10xf32>) -> tensor<10x10xf32>
    return %0 : tensor<10x10xf32>
  }
}
이를 타일링된 루프로 변환하려면 다음과 같은 여러 변환 패스가 필요합니다:
--convert-tensor-to-linalg: 텐서 연산을 linalg 다이얼렉트로 변환합니다--linalg-generalize-named-ops: (matmul 같은) 이름 있는 연산을 일반 linalg 연산으로 변환합니다--one-shot-bufferize="bufferize-function-boundaries": 텐서 연산이 버퍼를 사용하도록 변환합니다--buffer-deallocation-pipeline: 버퍼 해제를 처리합니다--convert-bufferization-to-memref: 버퍼 연산을 memref 연산으로 변환합니다--convert-linalg-to-affine-loops: linalg 연산을 affine 루프로 낮춥니다--affine-loop-tile="tile-size=5": affine 루프를 크기 5로 타일링합니다--canonicalize --cse: 정리 패스입니다
전체 변환 파이프라인은 다음과 같습니다:
mlir-opt tiling.mlir \
  --convert-tensor-to-linalg \
  --linalg-generalize-named-ops \
  --one-shot-bufferize="bufferize-function-boundaries" \
  --buffer-deallocation-pipeline \
  --convert-bufferization-to-memref \
  --convert-linalg-to-affine-loops \
  --affine-loop-tile="tile-size=5" \
  --canonicalize \
  --cse \
  -o tiling-transformed.mlir
그 결과 다음과 같은 타일링된 구현이 생성됩니다:
#map = affine_map<(d0) -> (d0)>
#map1 = affine_map<(d0) -> (d0 + 5)>
module {
  func.func @matmul(%arg0: memref<10x10xf32, strided<[?, ?], offset: ?>>, %arg1:
  memref<10x10xf32, strided<[?, ?], offset: ?>>, %arg2: memref<10x10xf32,
  strided<[?, ?], offset: ?>>) -> memref<10x10xf32, strided<[?, ?], offset: ?>>
  {
    affine.for %arg3 = 0 to 10 step 5 {
      affine.for %arg4 = 0 to 10 step 5 {
        affine.for %arg5 = 0 to 10 step 5 {
          affine.for %arg6 = #map(%arg3) to #map1(%arg3) {
            affine.for %arg7 = #map(%arg4) to #map1(%arg4) {
              affine.for %arg8 = #map(%arg5) to #map1(%arg5) {
                %0 = affine.load %arg0[%arg6, %arg8] : memref<10x10xf32, strided<[?, ?], offset: ?>>
                %1 = affine.load %arg1[%arg8, %arg7] : memref<10x10xf32, strided<[?, ?], offset: ?>>
                %2 = affine.load %arg2[%arg6, %arg7] : memref<10x10xf32, strided<[?, ?], offset: ?>>
                %3 = arith.mulf %0, %1 : f32
                %4 = arith.addf %2, %3 : f32
                affine.store %4, %arg2[%arg6, %arg7] : memref<10x10xf32, strided<[?, ?], offset: ?>>
              }
            }
          }
        }
      }
    }
    %alloc = memref.alloc() : memref<10x10xf32>
    %cast = memref.cast %alloc : memref<10x10xf32> to memref<10x10xf32, strided<[?, ?], offset: ?>>
    memref.copy %arg2, %alloc : memref<10x10xf32, strided<[?, ?], offset: ?>> to memref<10x10xf32>
    return %cast : memref<10x10xf32, strided<[?, ?], offset: ?>>
  }
}
타일링된 출력을 보면 원래의 10x10 행렬 곱셈이 더 작은 5x5 타일로 나뉘어 있으며, 이는 캐시 활용도와 메모리 접근의 지역성을 개선하는 데 도움이 됩니다.